Baseline import
The baseline is the expected quantity — what your system says should be on the shelf — for one Inventory. The work is split: the admin owns the template, the supervisor uploads the file.
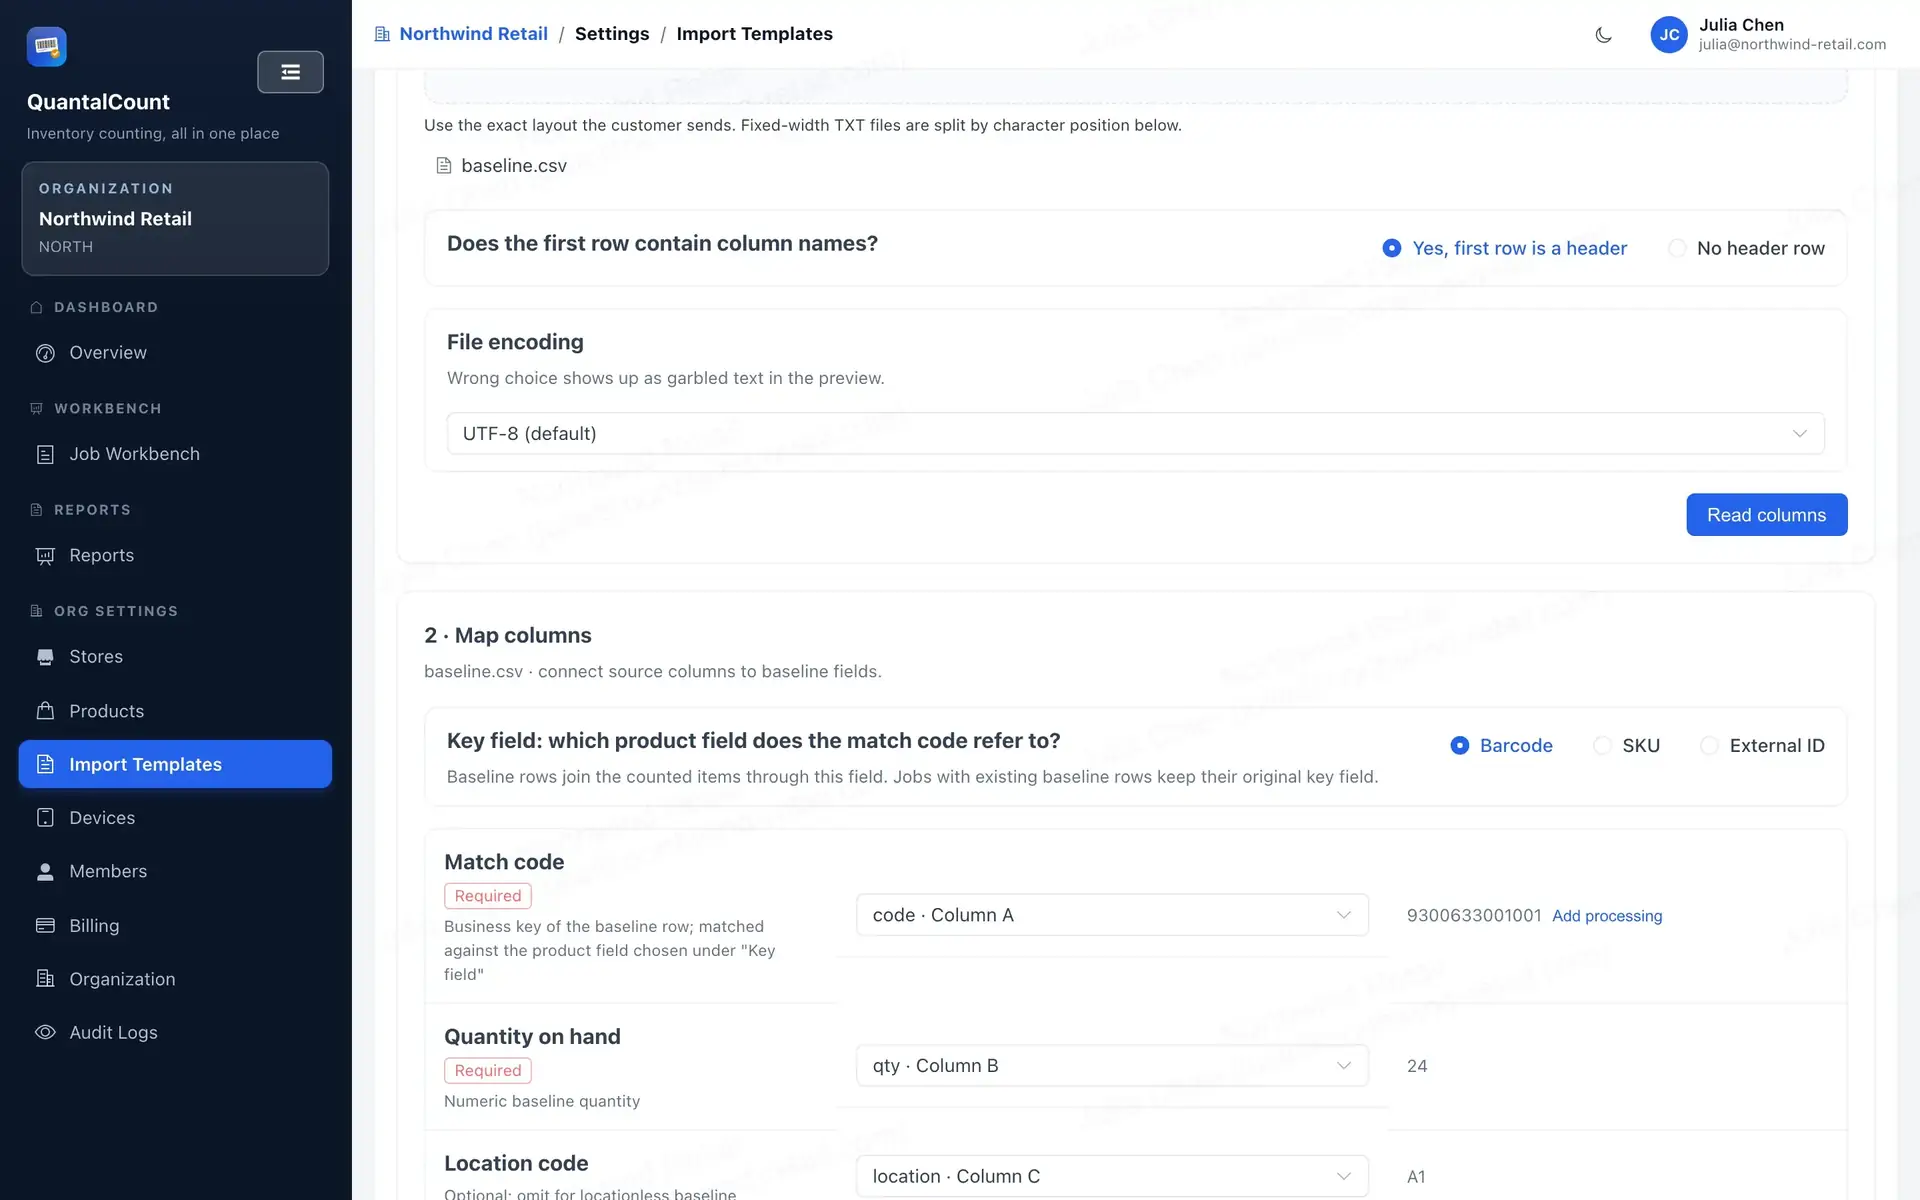
The template (Design Templates → Import Templates → Baseline)
One template per organisation:
- Match field — what do the codes in your file stand for:
barcode(the default),sku, orexternalId? - Column mapping:
- Must map: the code column and the quantity column
- Can map: location, retail price, product name, description
- Fix-up rules are only allowed on the code column
- Encoding, fixed-width layout, and so on — see File formats & encodings
No template yet? Uploads fall back to guessing standard column headers like code, barcode, sku, 商品码, 数量, qty, 货位, 品名, 描述.
Uploading (Supervisor, Inventory → Baseline)
Upload while the Inventory is Scheduled, Approved or Active — Closing doesn't accept baseline imports.
- Preview first. Up to the first 50 data rows are checked and labelled: matched, unmatched, ambiguous, or invalid. Product-match statuses are advisory: unmatched and ambiguous rows are still imported. Invalid rows are skipped during apply, and the final error report can also include duplicate-key or location errors outside the preview sample.
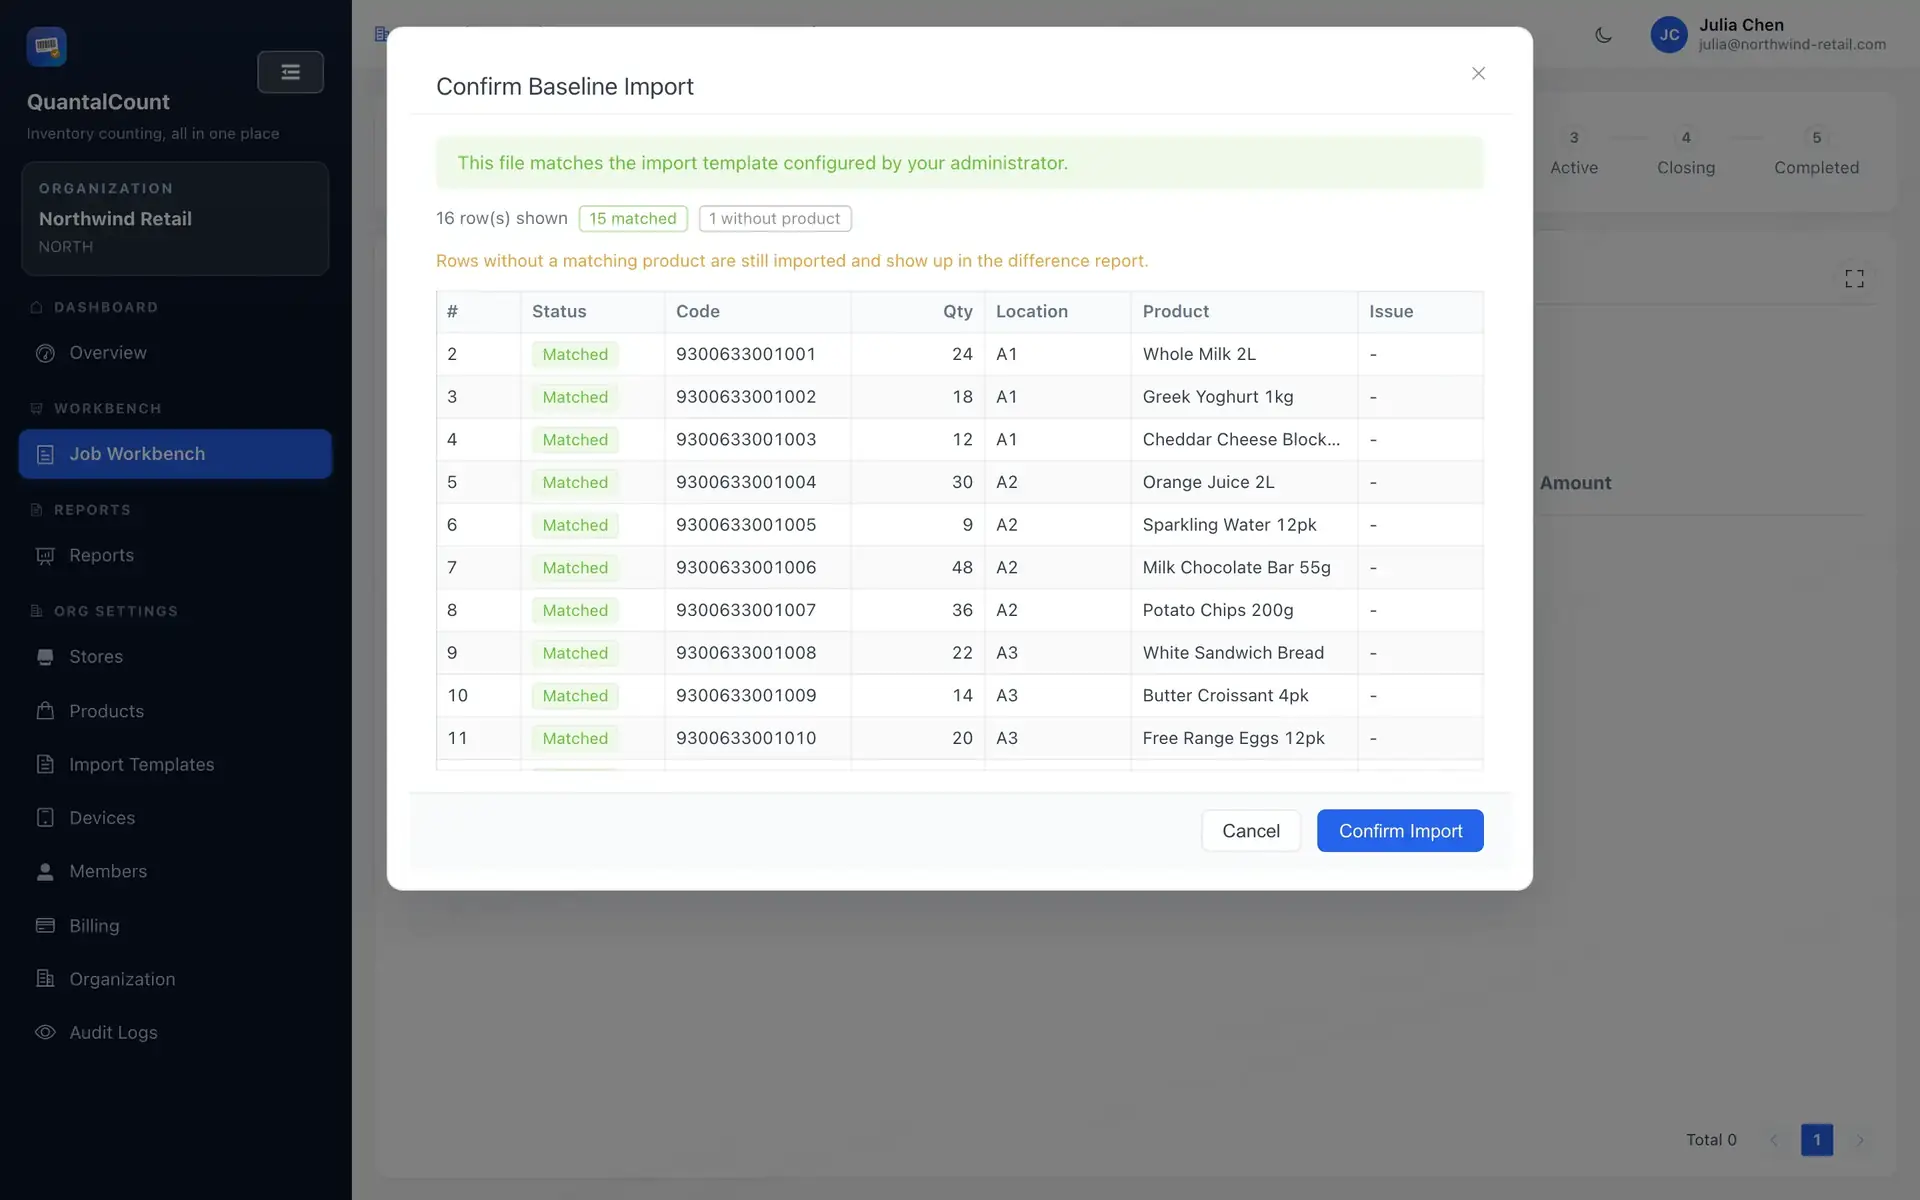
- Apply. The Inventory's entire baseline is replaced in one go.
What "replace" really means
- Applying an import replaces the Inventory's entire baseline with the file's applicable rows. Invalid rows and later duplicate or location-error rows are skipped; codes without a product in the bound catalogue are still retained.
- Duplicate detection uses the normalised code and location. At the same location — or when both rows have no location — the first row wins and later duplicates are skipped and reported. One file can't mix rows with locations and rows without locations.
- No product is assigned to a Baseline row during apply. When a report runs, the cleaned-up file code is compared only within the Inventory's bound catalogue, against the single barcode, SKU or external ID field selected for that import. There is no scan-style fallback across fields. If several products match, the product with the smallest Product ID is used and the key is also marked ambiguous. If none match, the report falls back to the name and description from the file. Later catalogue changes can therefore change subsequent report matching.
- Because each import remembers its own match field and file contents, old and new baselines never get mixed up.
Common problems
- Everything shows as unmatched? Usually the match field is wrong — the file has SKUs but the template says barcode — or a fix-up rule is missing (like dropping a check digit). Fix the template and upload again; the new upload fully replaces the old data.
- Fixed-width TXT rejected? Those files need a template with column widths filled in. There's no guessing.
- Garbled characters? Pick the right encoding in the template (for older Chinese systems, that's often
gb18030).